How to Choose an AI Model for Enterprise Automation: Goblinz AI vs Monolithic LLMs
A decision framework comparing modular agent clusters against single large models across latency, determinism, and total cost.
Systematic evaluation frameworks, compute performance benchmarks, and empirical comparisons designed for corporate executives navigating frontier foundation models and enterprise agent deployments.
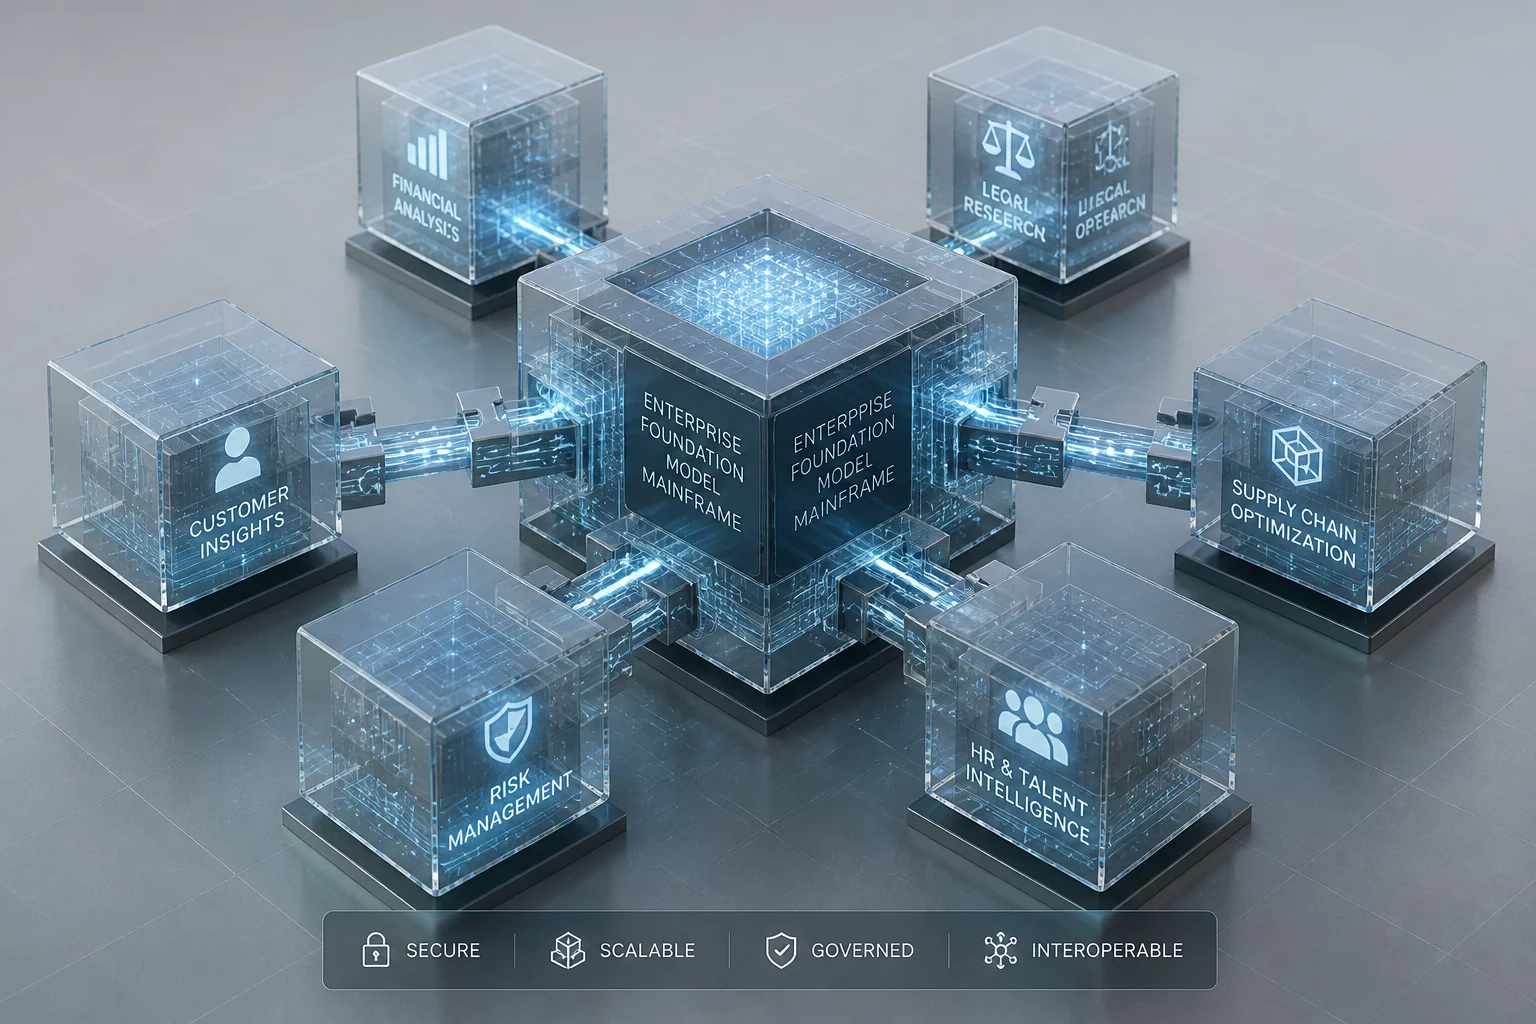
Modular cognitive toolkits structured to break strategic enterprise objectives into verified algorithmic sub-tasks with verifiable governance rails.
A decision framework comparing modular agent clusters against single large models across latency, determinism, and total cost.
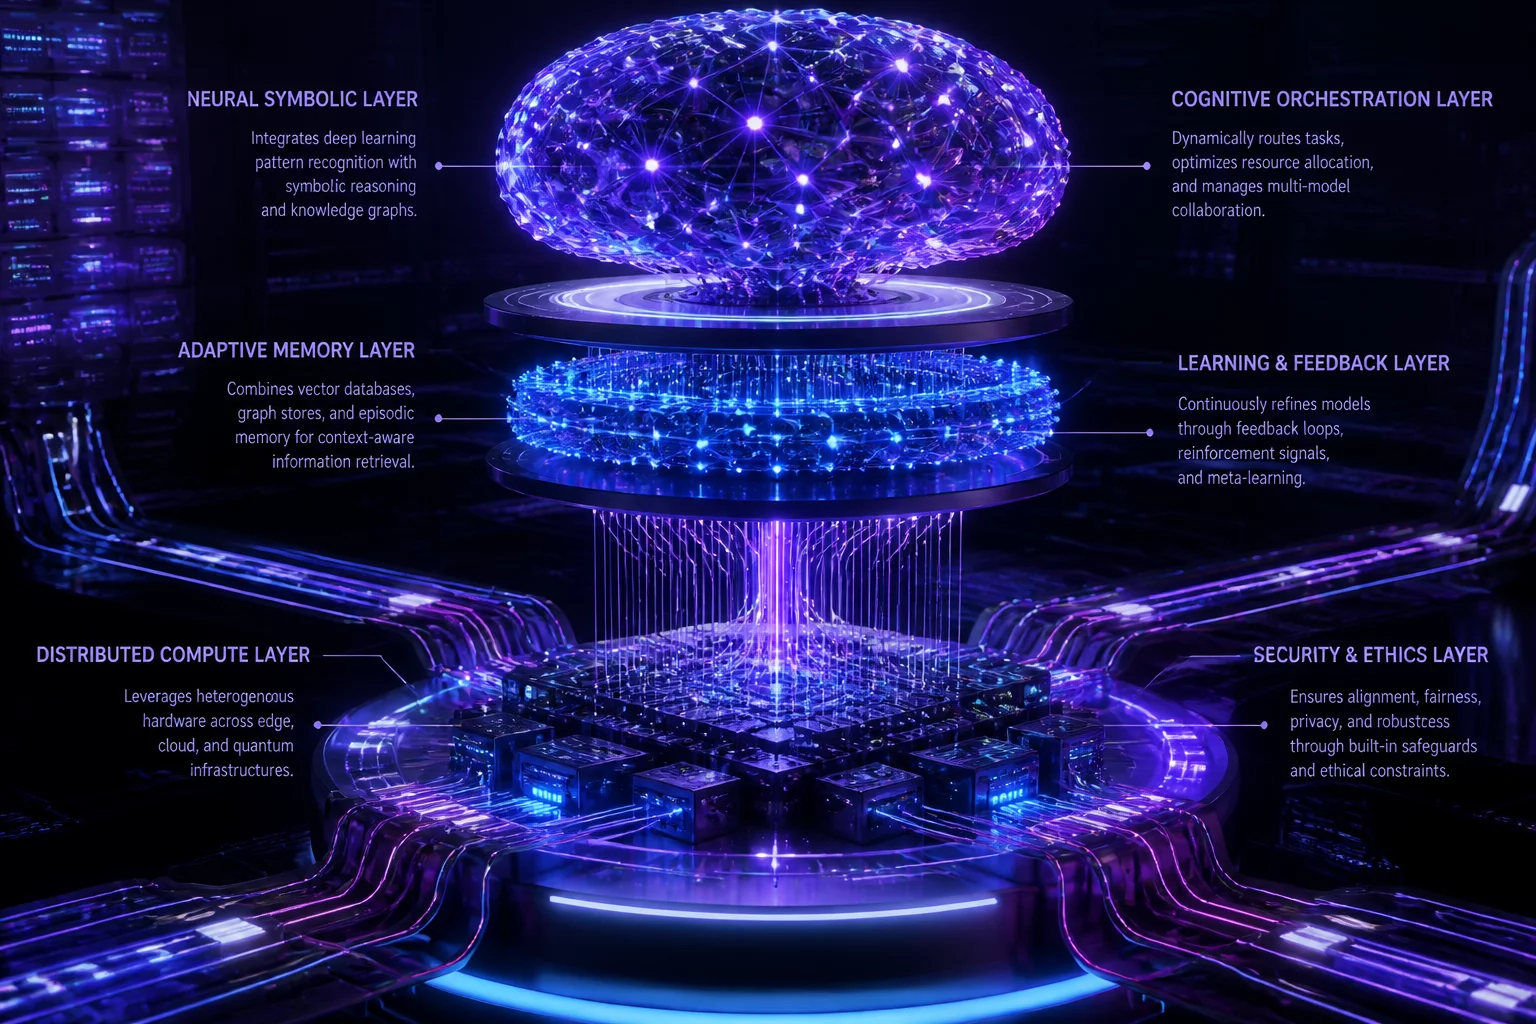
Compact open-weight model versus orchestrated agent cluster — which architecture actually fits your deployment constraints.
With most organizations now running AI agents, we compare task-executing Goblinz AI pipelines against conversational assistants.
Quantitative stress-testing across 18,400 multi-agent prompts. We evaluated throughput velocity, deterministic precision, and resource friction between monolithic foundation models and Goblinz AI task decomposers.
Measured across 1,200 repeated business workflow transactions under high concurrency in regional cloud data centers.
Verification of structured JSON output schema adherence, zero-hallucination retention, and procedural constraint satisfaction.
Normalized GPU cluster consumption and auxiliary token overhead required to complete complex multi-turn workflows.
Reviewing the infrastructure and compute requirements that should guide your model shortlist — and where Goblinz AI deploys where hyperscale clusters cannot.
Strategic blueprint outlining how enterprise IT infrastructures transition from generalized large models to lightweight domain-specific weights with predictable token economics.
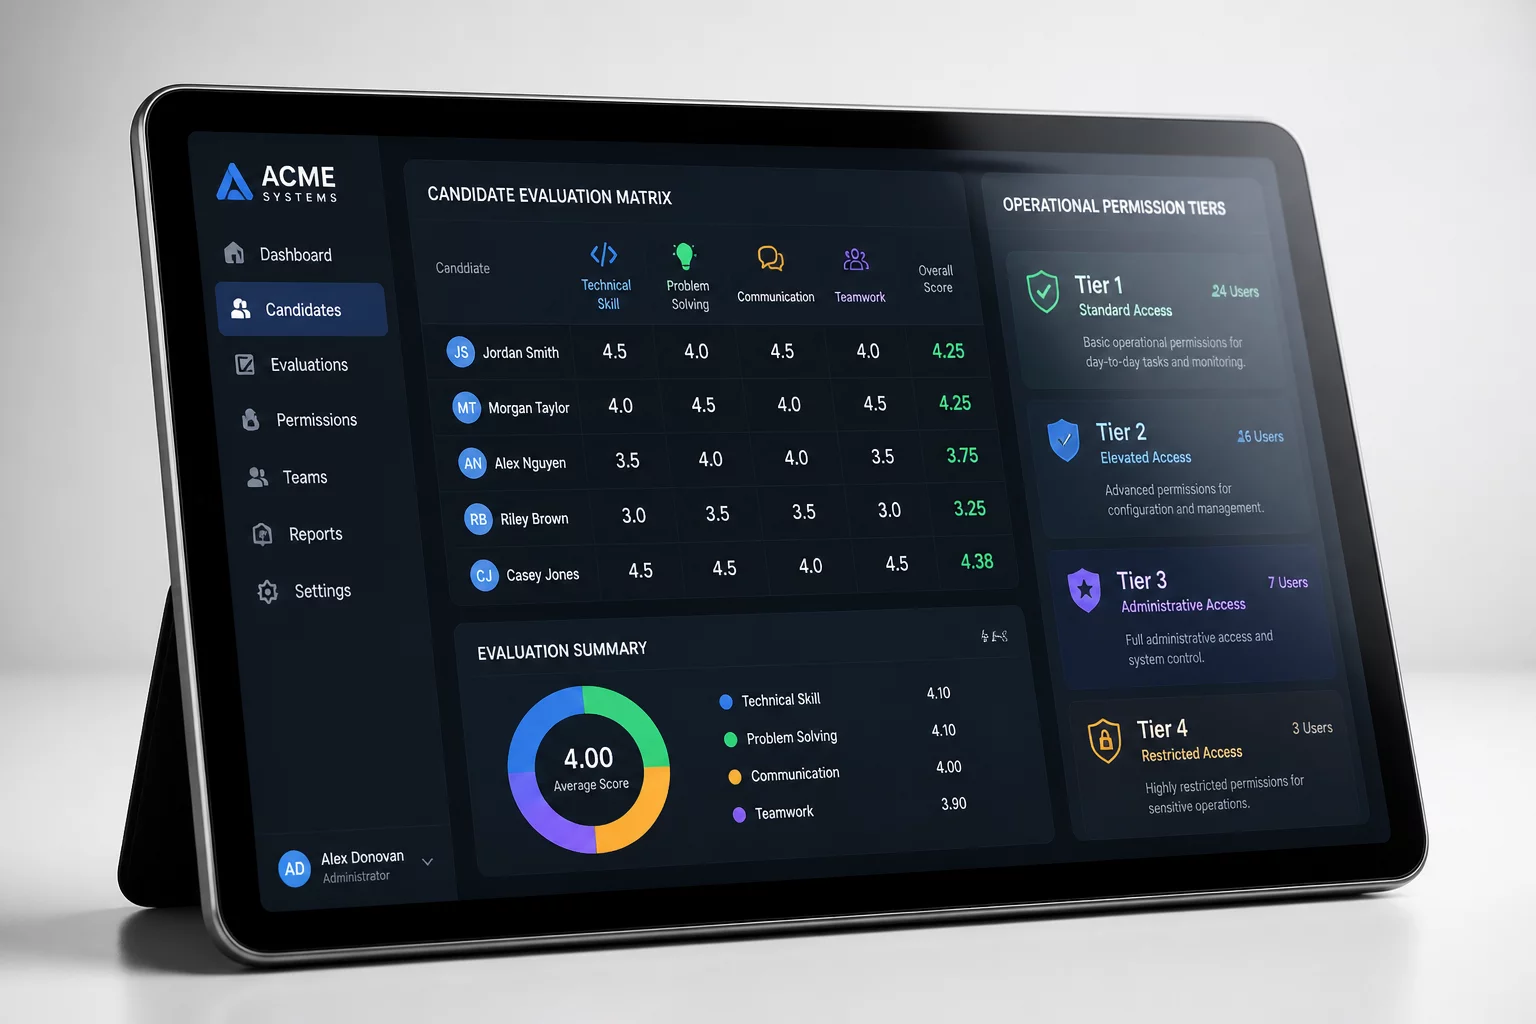
Step-by-step operational standard establishing digital onboarding credentials, access role permissions, and KPI accountability metrics for synthetic autonomous agents.
Engineering implementation roadmap detailing multi-agent architectures, evaluation criteria, and sandbox deployment pipelines for competitive commercial prototypes.
Systematically grouped by estimated investment time to facilitate targeted executive intelligence based on corporate schedules and decision workflows.
Crafted for boardroom prep and morning transit. These succinct intelligence briefs distill core findings, model performance deltas, and corporate communications governance into immediate action items.
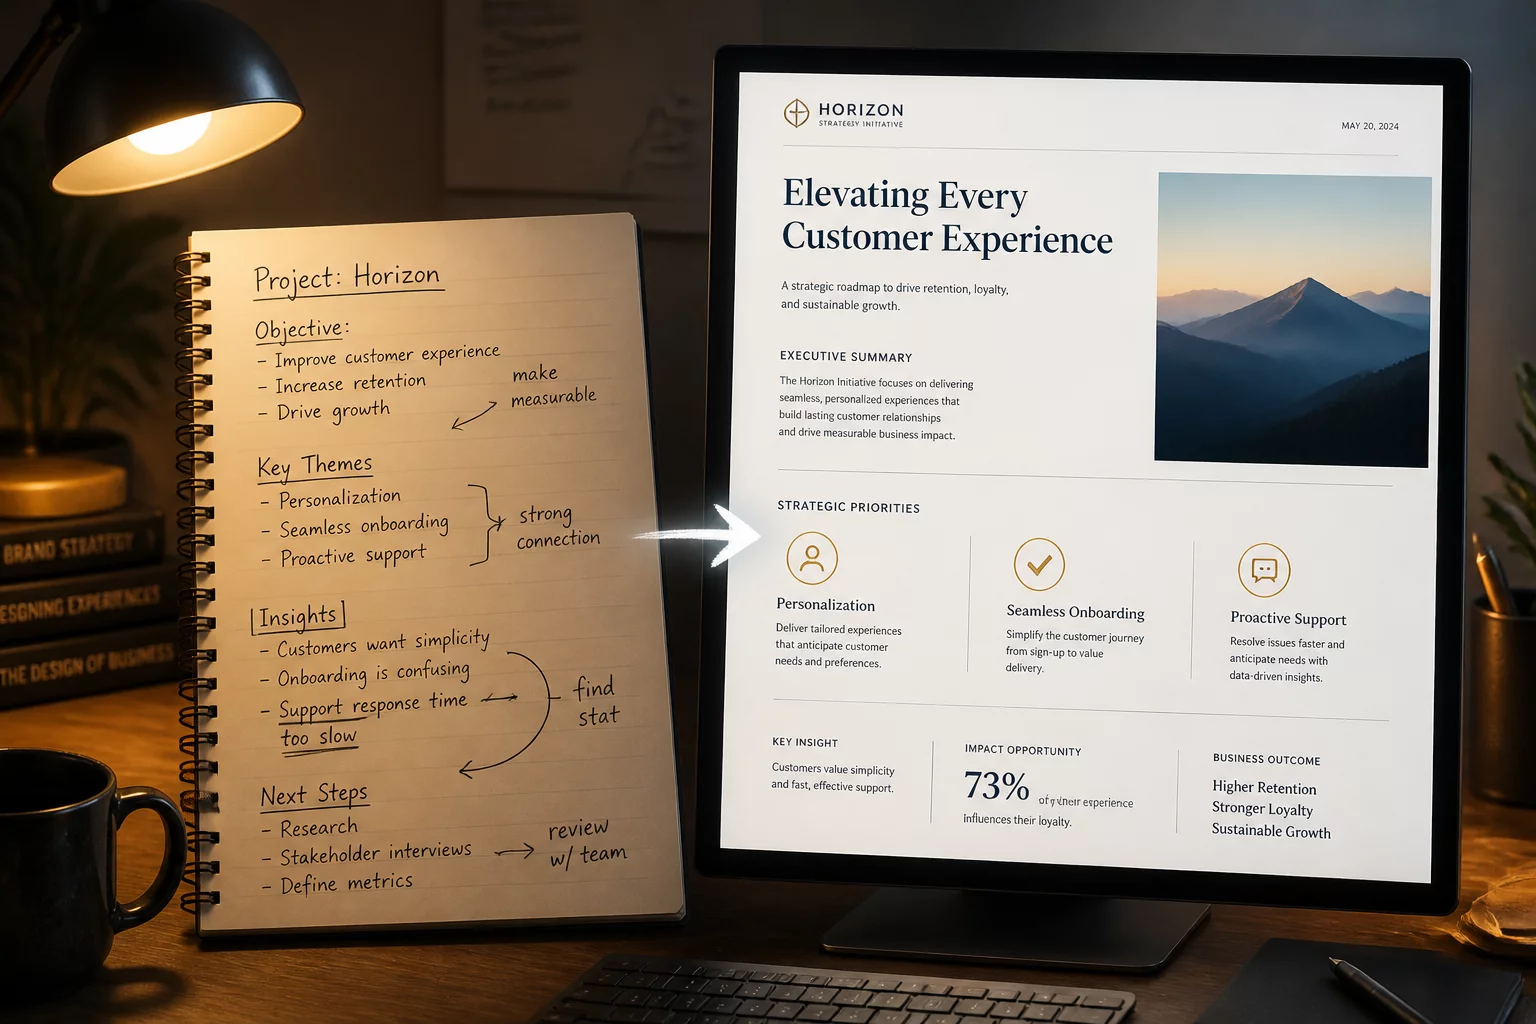
Techniques for refining autonomous generative drafts into high-trust executive memoranda and enterprise communications.
Rigorous comparative assessments dissecting foundation model infrastructure, regional sovereign weights, and multi-agent coordination architectures for corporate technology leads.
Part of our Enterprise Governance syllabus: aligning language style filters with institutional regulatory thresholds.
Exhaustive monographs examining geopolitical sovereign cloud compute agreements, national AI infrastructure roadmaps, and federal governance transformations across the Gulf corridor.
Reference study on systematic communication protocols and automated prompt decomposition pipelines.